Conversational Document
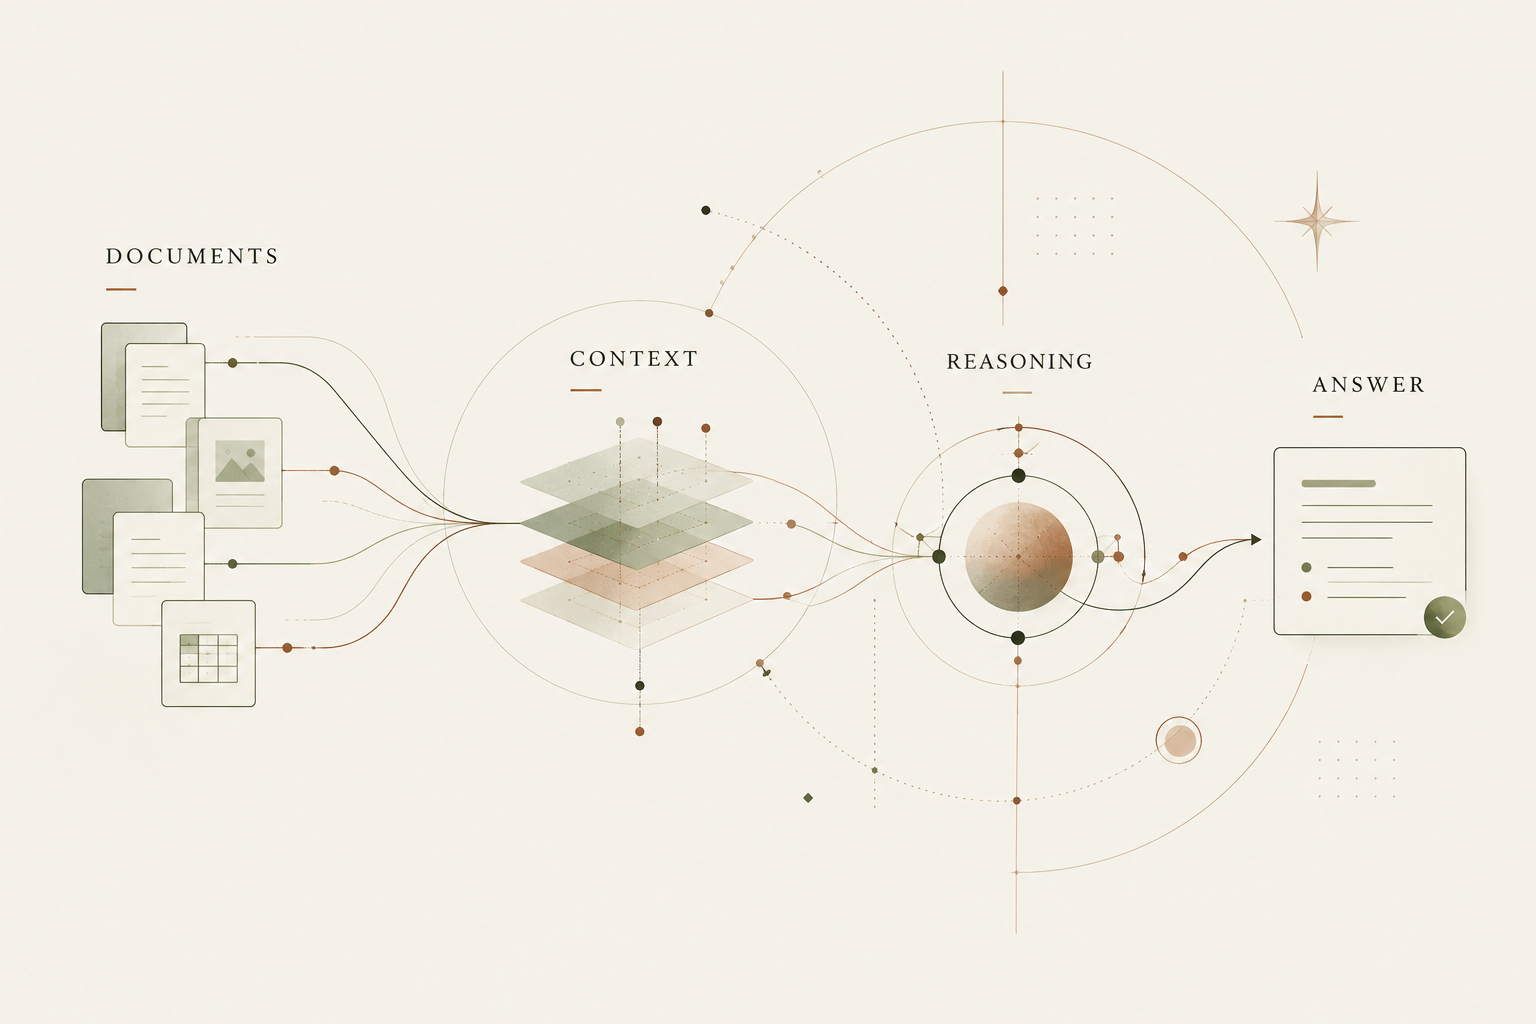
Retrieval System
Making large enterprise document repositories easier to explore through grounded, conversational search.
Explore case studyFull Stack Gen AI Engineer Building Scalable AI Solutions Kolkata, West Bengal, India
I build LLM-powered products that connect useful ideas to dependable systems—from conversational document retrieval to agents that make business data easier to reach.
Retrieval, reasoning, and the details that make them useful.
01 The practice
Full Stack Generative AI Engineer specializing in scalable AI systems and enterprise-grade RAG architectures.
Designed and delivered reliable multi-LLM orchestration pipelines, conversational AI systems, and intelligent document processing solutions. Strong expertise in backend engineering (Django, FastAPI), vector search, and production optimization. Passionate about building reliable, high-impact AI applications.
More about my experience02 Selected work
A selection of AI engineering work, described through the problems, architecture, and implementation behind each system.
Making large enterprise document repositories easier to explore through grounded, conversational search.
Explore case studyTurning natural-language questions into schema-aware SQL with generation, validation, and refinement.
Explore case studyHelping quality teams review lab-report parameters against regulatory thresholds and spot discrepancies.
Explore case studyEarlier work Academic projects
A couple of earlier projects developed alongside my studies.
It's a Django-based Blog App where users can create, publish, and manage posts. Features include a user-friendly admin panel, tagging system, RSS feed, search, email sharing, commenting, and tag-based post recommendations.
Associated with Maulana Abul Kalam Azad University of Technology, West Bengal (formerly WBUT)
Tools Django, django-taggit, psycopg2, markdown
This project is built to scrape a Wikipedia page based on the topic provided by the user and display a summarized version of the topic along with all the reference and image links. It will help the user to learn about the topic in a shorter amount of time.
Associated with Maulana Abul Kalam Azad University of Technology, West Bengal (formerly WBUT)
Tools Selenium, Flask, JSON, NLTK, ChromeDriverManager, etc.
03 Behind the systems
Each project starts with a practical problem. Here’s how the pieces fit together.
Retrieval · Conversation · Context
Business users needed a more accessible way to find information across enterprise document repositories.
Qdrant vector retrieval paired with embedding models via Azure OpenAI and Vertex AI, coordinated through a multi-step LangGraph pipeline with conversational memory.
Designed chunking and retrieval, built Django/DRF backend APIs, and developed a responsive chat interface for real-time querying.
Reduced document-search effort and improved information accessibility for business users; no quantitative result was specified.
Orchestration · Validation · Data access
Make relational business data easier to query without requiring every user to write SQL manually.
A multi-LLM workflow using Azure OpenAI and Gemini through Vertex AI for query generation, validation, and refinement.
Added schema-aware prompting and structured output parsing, then connected query execution to a results dashboard with conversational follow-ups.
Accelerated business data access and reduced dependence on manual SQL querying; no quantitative result was specified.
Document intelligence · Rules · Reporting
Quality teams needed to check lab-report values against FSSAI regulatory thresholds and identify discrepancies.
An AI-driven document-intelligence workflow combining LLM-based structured parameter extraction with rule-based validation.
Built parameter extraction, threshold comparison, discrepancy detection, and reporting workflows for QA teams and vendors.
Reduced manual compliance-verification effort while improving accuracy and turnaround time; no numeric measurements were provided.
04 Experience
A path through full-stack development, applied AI, and systems designed to make everyday work a little easier.
ITC Infotech · Kolkata, West Bengal, India
Designing and deploying scalable Generative AI systems for enterprise clients, including conversational RAG architectures, multi-LLM NL-to-SQL pipelines, and AI-driven document intelligence agents. Responsible for backend system design, vector search integration, conversational memory implementation, and production optimization using Azure OpenAI and Vertex AI.
AM Infoweb Pvt. Ltd. · Pune District, Maharashtra, India
05 Technical expertise
From a model call to the application around it, I enjoy bringing the full system into focus.
Generative AI, Retrieval-Augmented Generation (RAG), Agentic AI Development, LangChain, LangGraph, Google ADK, Azure OpenAI, Vertex AI, HuggingFace, OpenRouter, Ollama, LiteLLM, Qdrant, BM25, ColBERT, ColPali, hybrid retrieval, embeddings, metadata filtering, MCP, conversational memory, HITL workflows, guardrails, structured outputs, response evaluation.
Python, Django, Django REST Framework, FastAPI, REST APIs, PostgreSQL, MySQL, MongoDB, Redis, Apache Kafka, asynchronous processing, multiprocessing, multithreading, schema design, query optimization, unit testing.
HTML, CSS, JavaScript, Bootstrap, jQuery, Streamlit, responsive interfaces, AJAX/fetch, dynamic rendering, data visualization integration, pagination, lazy loading, Selenium UI automation.
Microsoft Azure OpenAI, Google Cloud Platform, Vertex AI, Docker, Git, GitHub, GitLab, service-account-based cloud integration.
06 Learning & foundations
Maulana Abul Kalam Azad University of Technology, West Bengal (formerly WBUT)
Oct 2020 – Jun 2022 · 1st Class
University of Calcutta
Jun 2016 – Jun 2019 · 1st Class
Score: 103 · Oct 2020 · AIR 29
The next good question
Interested in thoughtful GenAI engineering and practical product work? I’d be glad to connect.